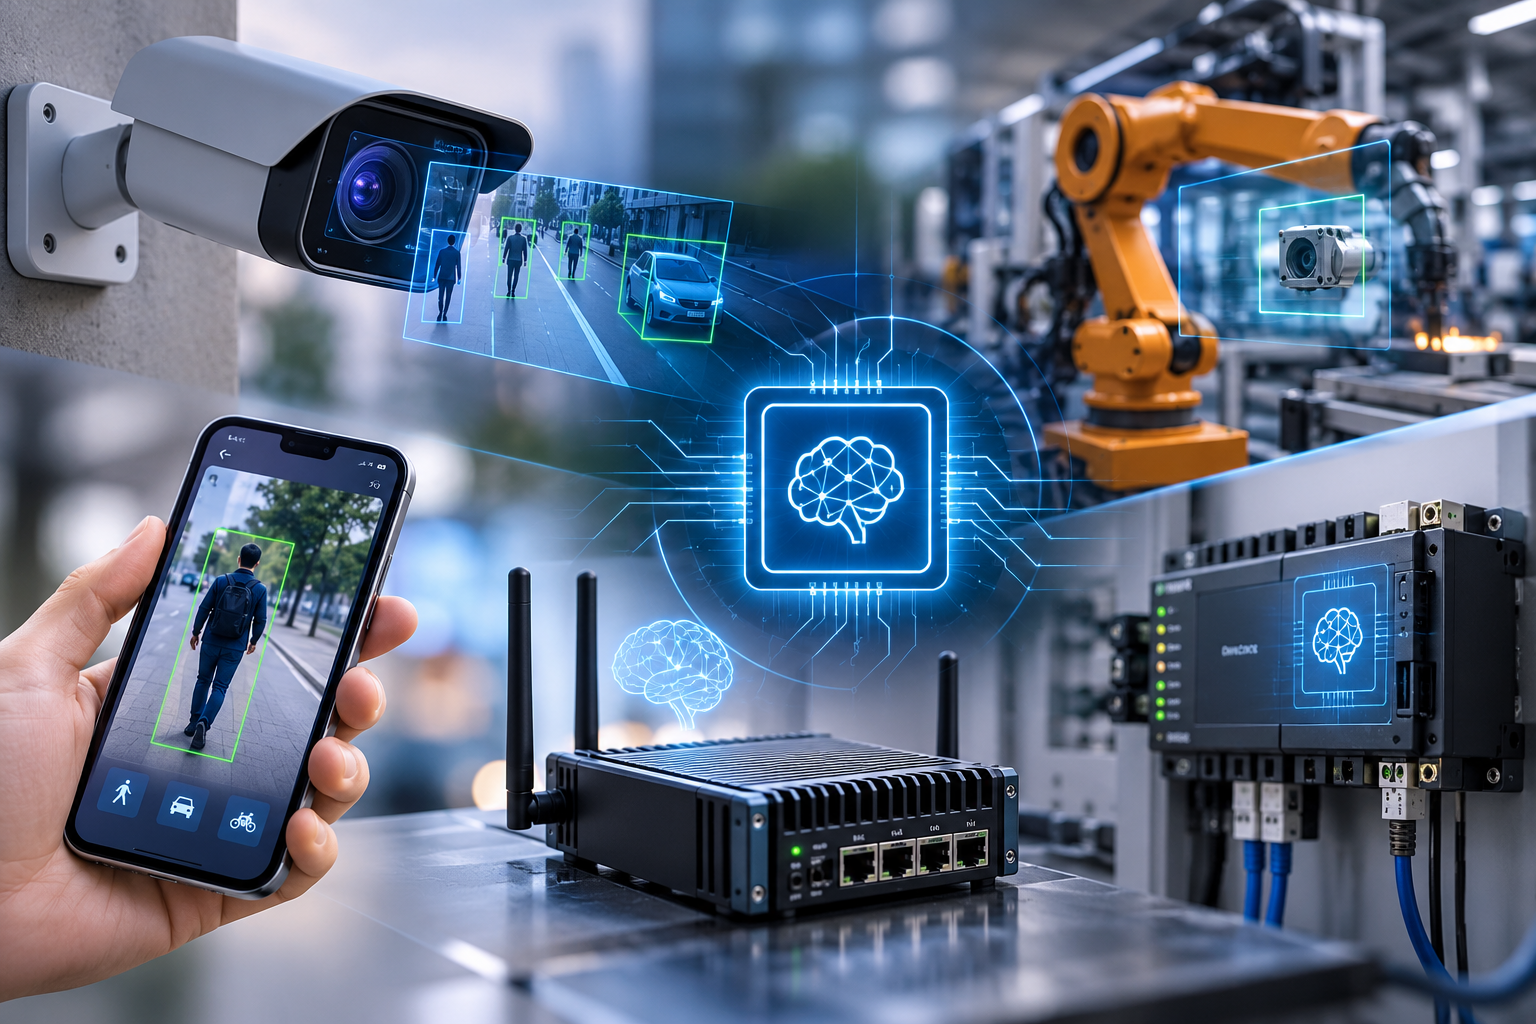
On-Device AI
Run neural networks fully on phones, gateways, cameras, and industrial controllers so decisions happen locally without round-trips to the cloud.
We deploy intelligence directly on devices and machines for low-latency decision-making, real-time perception, privacy, and reliable operation without constant dependence on cloud infrastructure.
Deploy models on devices and machines so intelligence runs at the source of data - with low latency, offline resilience, and strong privacy by design.
Run neural networks fully on phones, gateways, cameras, and industrial controllers so decisions happen locally without round-trips to the cloud.
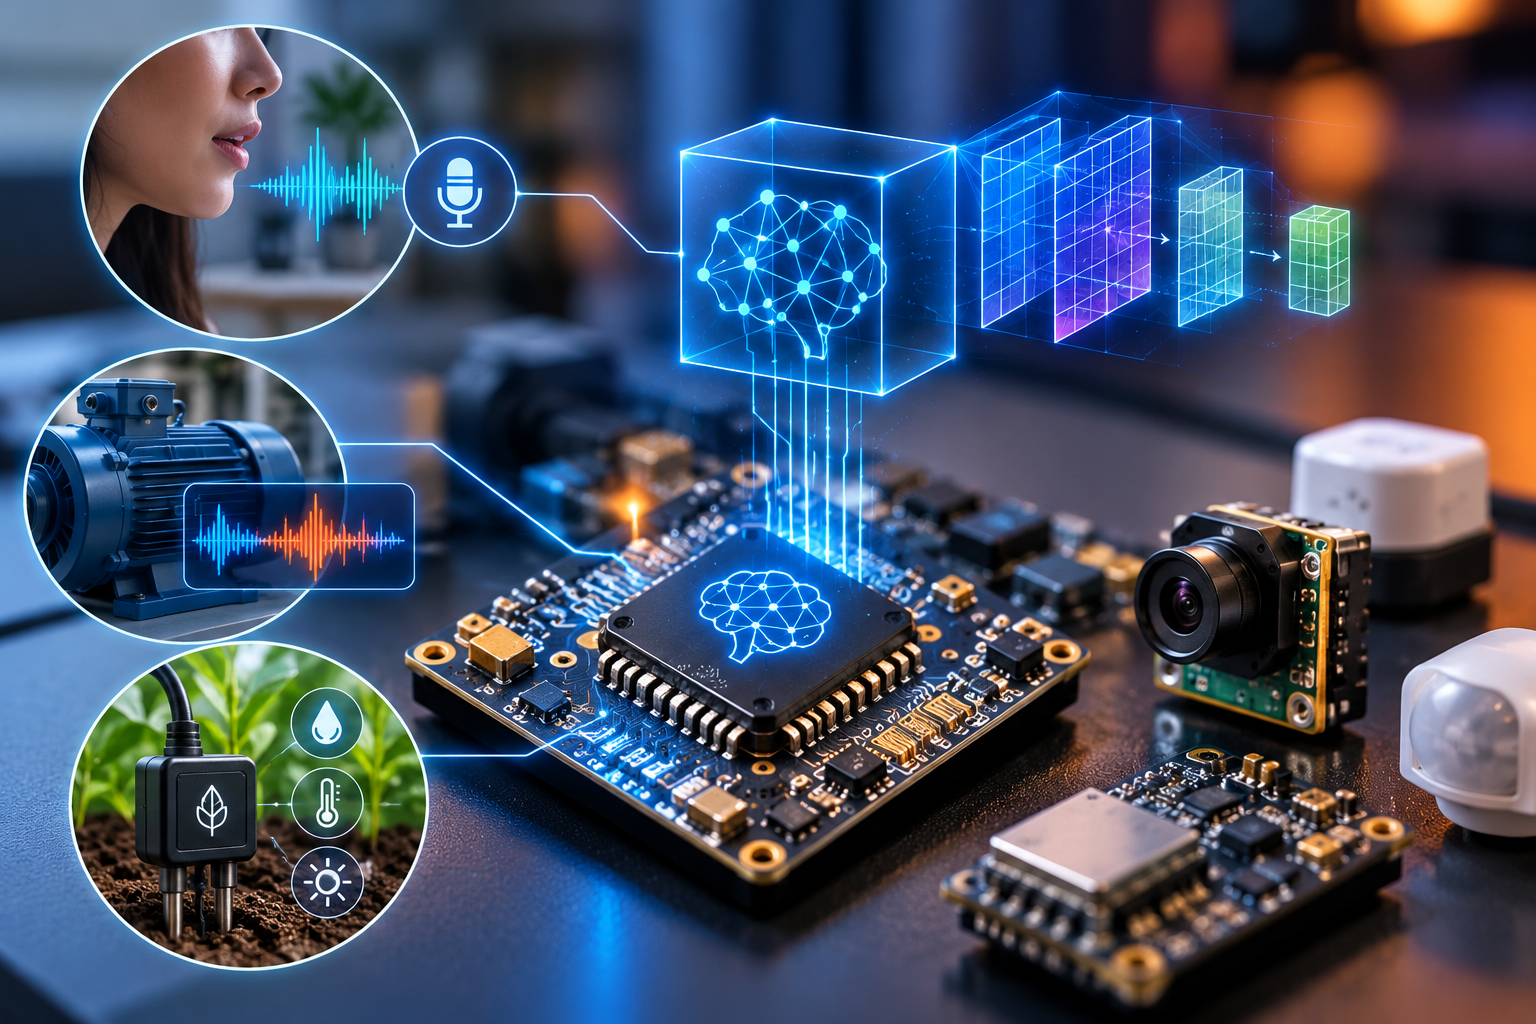
Compress and optimize models for microcontrollers and ultra-low-power chips - keyword spotting, anomaly detection, and sensing at milliwatt scale.
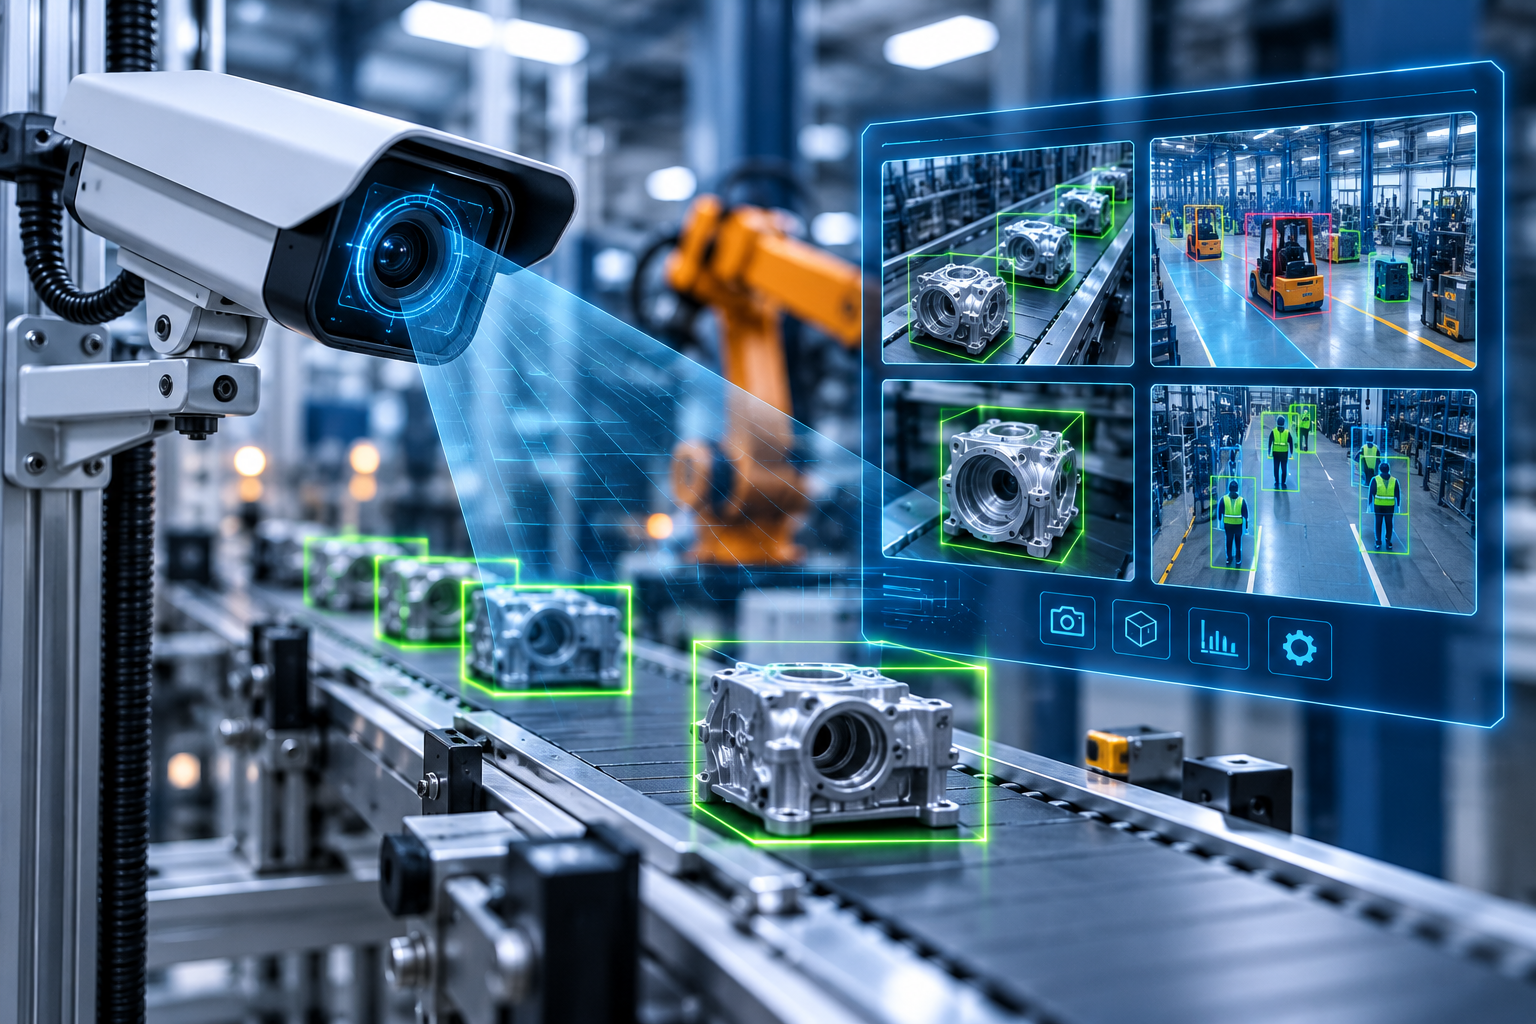
Deploy detection, classification, and tracking models on smart cameras and vision SoCs for real-time inspection, safety, and monitoring at the edge.
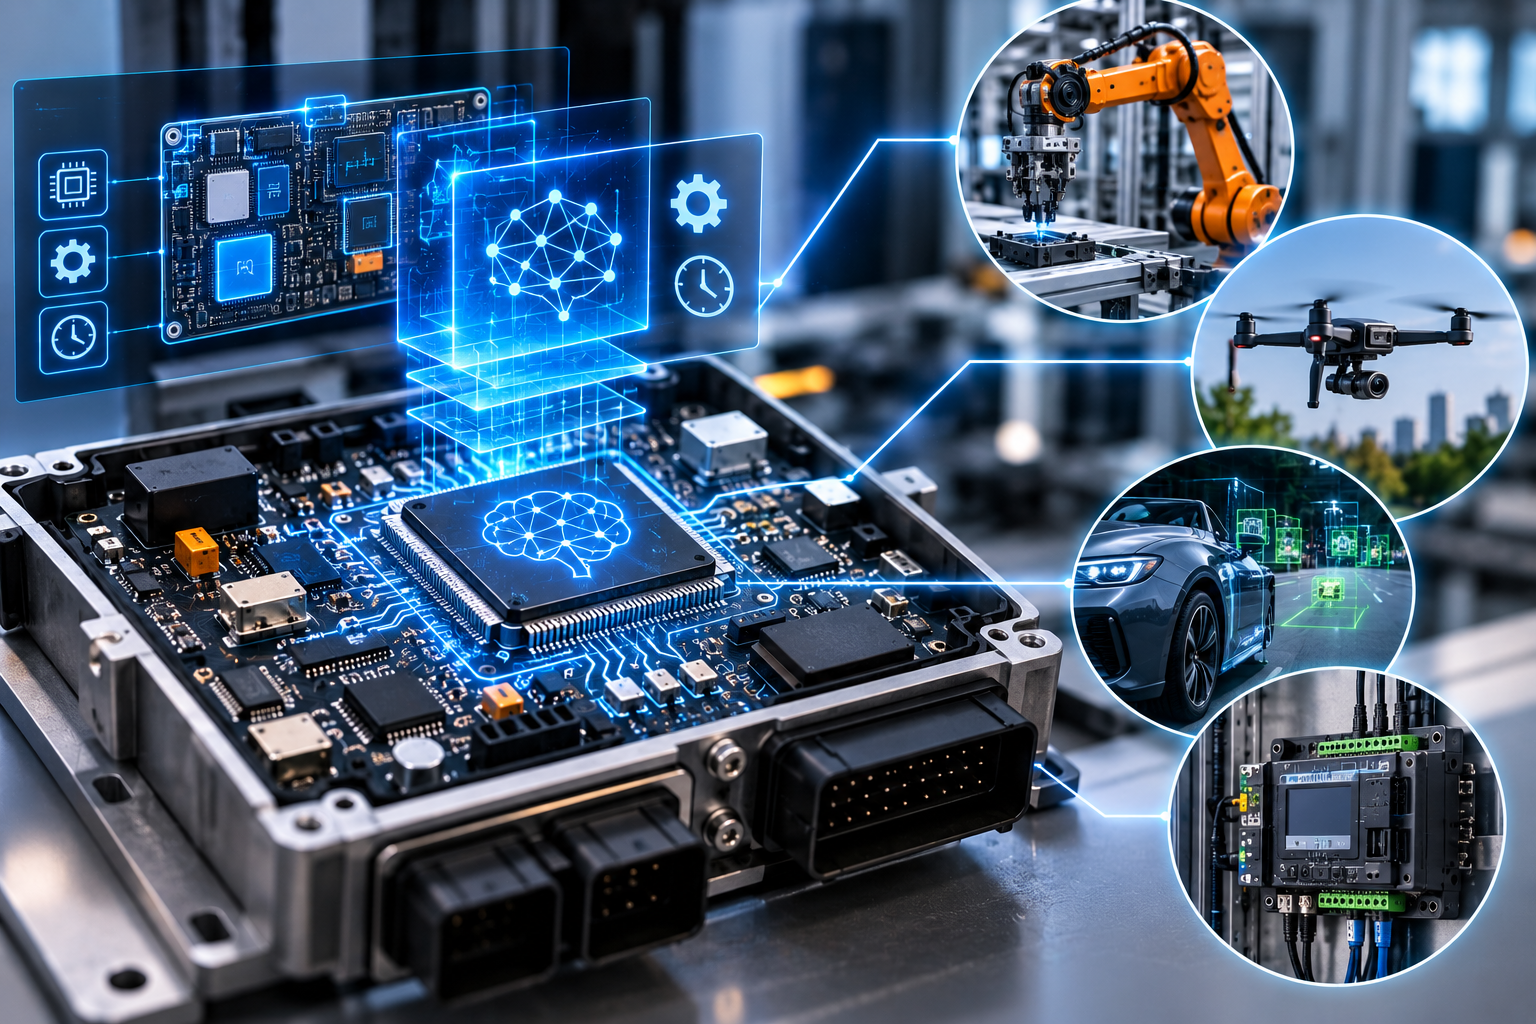
Integrate AI into firmware and RTOS-based systems with constrained memory, deterministic timing, and long product lifecycles.
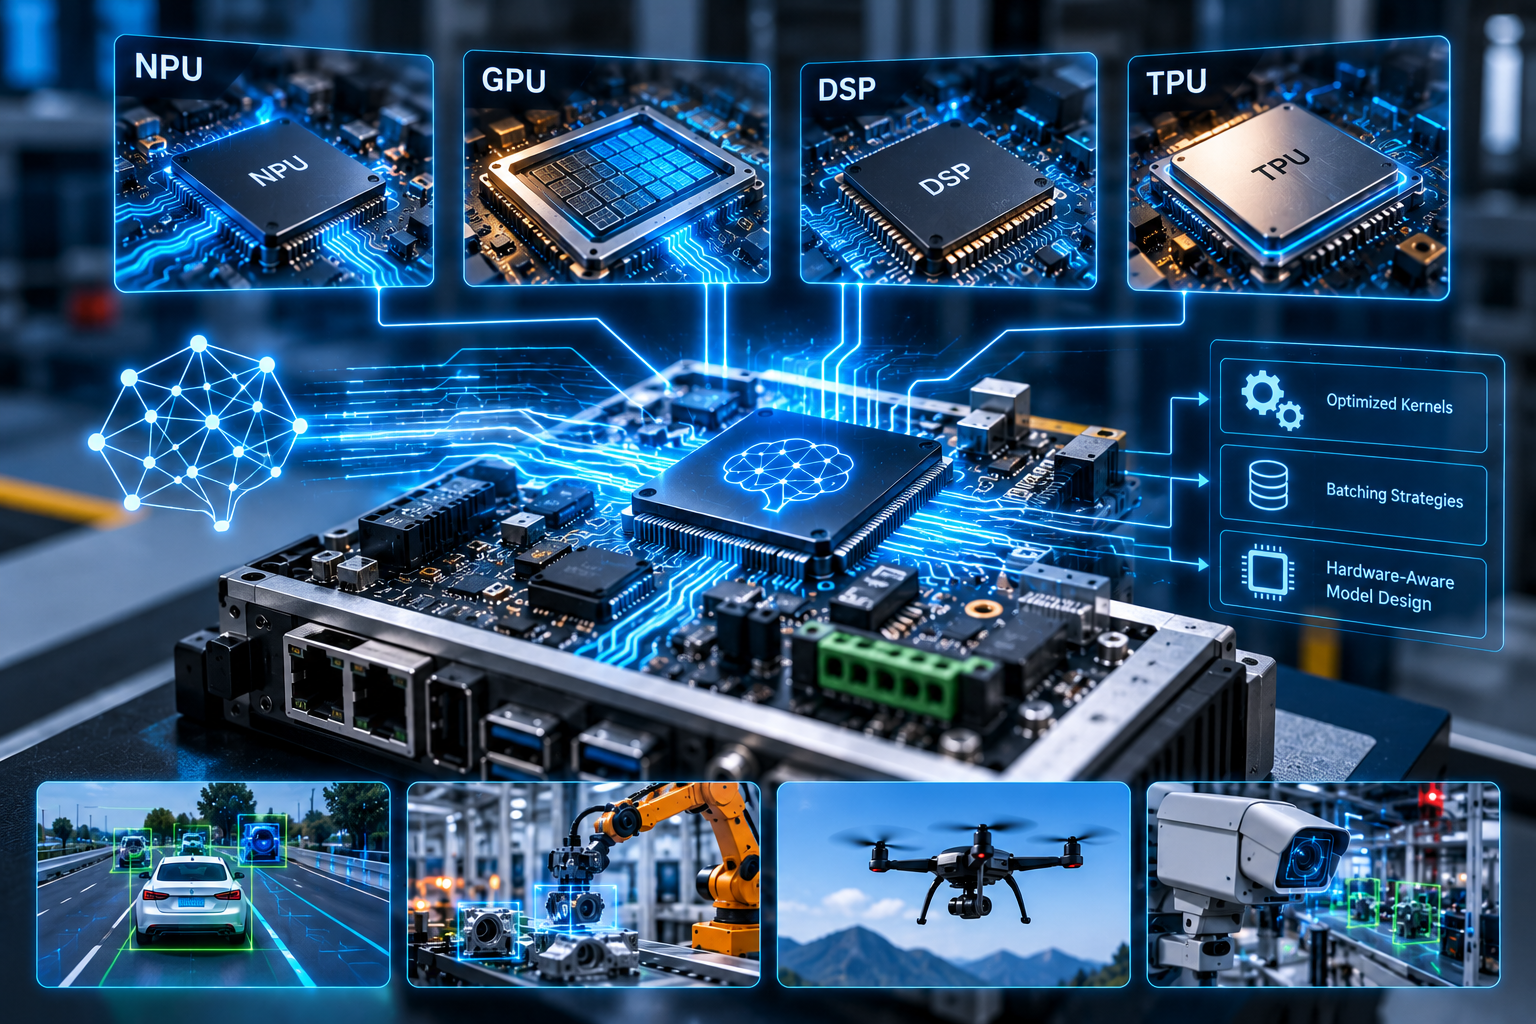
Target NPUs, TPUs, DSPs, and GPUs on edge silicon - with optimized kernels, batching strategies, and hardware-aware model design.
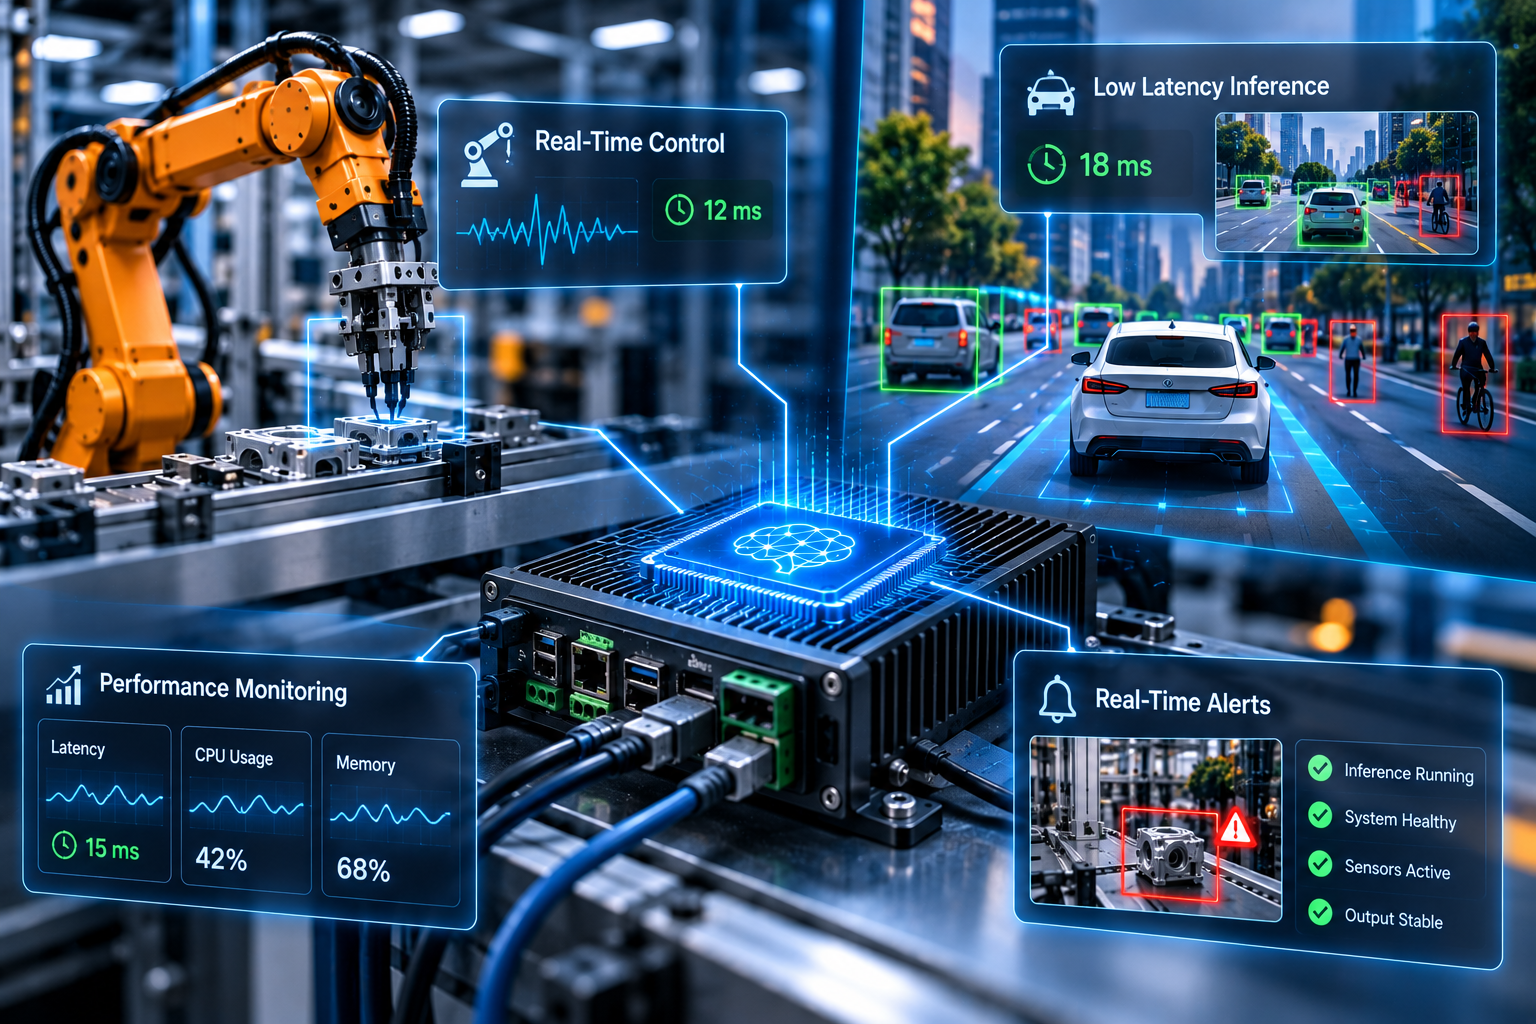
Meet strict latency budgets for control loops, alerts, and interactive experiences - with profiling, scheduling, and continuous monitoring on device.
Define latency, power, memory, and connectivity limits for the target device and use case.
Choose or design architectures that fit edge budgets while meeting accuracy requirements.
Apply pruning, distillation, and INT8/INT4 quantization to shrink models for device memory.
Compile and optimize for NPUs, GPUs, DSPs, or CPUs using vendor toolchains and kernels.
Embed inference into firmware, RTOS, or edge OS with sensors, buffers, and I/O pipelines.
Measure latency, throughput, thermal, and power; tune batch size, threads, and clocks.
Test accuracy on device data, offline scenarios, and edge cases under real conditions.
Ship signed packages with secure boot, OTA paths, and fallback modes for field devices.
Monitor devices, retrain on edge data, and push incremental model updates over time.
Measurable results from edge and on-device AI systems we design, optimize, and deploy in the field.


We select runtimes, toolchains, and silicon based on latency, power, memory, and long-term support for edge products.
Deploy on-device models, TinyML, edge vision, and real-time inference that work offline, stay private, and meet strict latency budgets.
Partner with our engineers to build on-device AI, TinyML, edge vision, and accelerator-optimized inference that runs where your data and decisions live.